
Webinar
Who's actually spending your AI budget?
Related Solutions
Overview
Every line item in the technology budget has an owner, a forecast and a control. AI spend often has none of the three yet is quickly become one of the fastest-growing technology expenses. Many organizations still struggle to answer a basic question: who's responsible for AI spend?
In this on-demand session, Tracie Stamm, Sr. Director of Product Marketing at Flexera, and guest speaker Tracy Woo, Principal Analyst at Forrester, explore why AI cost accountability is becoming increasingly difficult as adoption expands across applications, models, agents, data platforms and infrastructure.
Learn why traditional approaches to cost management fall short, how agentic AI changes spending patterns and what organizations can do to establish visibility, governance and control before costs escalate.
Key takeaways
- AI cost accountability remains unclear. Unlike traditional technology investments, AI spending often spans multiple teams, platforms and use cases, making ownership and ROI difficult to define.
- Agentic AI is creating a new wave of cost complexity. Autonomous agents can drive significant consumption through repeated tool calls, chained workflows and growing infrastructure requirements.
- Visibility gaps make AI spending difficult to manage. Embedded AI charges, shared services, fragmented billing models and limited attribution create blind spots across the AI stack.
- AI costs extend far beyond model usage. Applications, agents, data platforms, infrastructure, GPUs and storage all contribute to total AI spend.
- Organizations need a governance framework, not just cost reporting. Standardized tagging, shared ownership models and consistent cost attribution are critical for sustainable AI adoption.
- Traditional cost management practices must evolve. Finance, engineering, FinOps and business teams all play a role in managing AI costs and demonstrating business value.
- The path forward starts with accountability. Leading organizations begin with visibility and attribution, then expand into governance, controls and automation over time.
Speakers
Tracie Stamm
Sr. Director Product Marketing, AI Cost Management
Flexera
Tracy Woo
Guest speaker
Principal Analyst
Forrester
From AI spending to AI accountability
Why AI costs are harder to manage
AI costs span applications, models, agents, data platforms and underlying infrastructure. With consumption distributed across teams and systems, traditional cloud bills and subscription reports cannot provide a complete picture.
Outcome: Organizations need a unified view of AI consumption across the full stack to understand total cost and make informed decisions.
How agentic AI changes the cost equation
AI agents can initiate repeated tool calls, trigger downstream workflows and consume resources without direct human interaction. These patterns make spending harder to predict, attribute and control.
Outcome: AI cost management must account for both human and non-human consumption, with controls that identify anomalies and prevent runaway spending.
Where AI cost accountability belongs
Finance sees what was billed. IT knows who has access. Engineering understands what was deployed. No single team has all the information needed to manage AI spending alone.
Outcome: Effective accountability requires shared ownership across finance, IT, engineering and business teams, supported by common cost and value data.
What closes the AI visibility gap
Embedded charges, shared services, inconsistent tagging and fragmented provider data make it difficult to connect consumption to a specific team, product or use case.
Outcome: Standardized tagging, use-case identifiers and normalized consumption data make AI costs easier to allocate, forecast and govern.
How AI spending connects to business value
Consumption data alone cannot show whether an AI investment is delivering meaningful results. Cost information needs context about the use case, owner and expected outcome.
Outcome: Connecting AI costs with ownership and value metrics helps teams evaluate ROI and make stronger investment decisions.
How to build an AI cost management practice
Organizations do not need to solve every AI cost challenge at once. The webinar outlines a phased approach that begins with baseline visibility and attribution, then adds governance, optimization and automated controls.
Outcome: Teams can establish an AI cost management practice that grows with adoption, moving from fragmented reporting to repeatable accountability and control.
Ready to take control of AI spending?
AI accountability starts with visibility. Whether you're revisiting key insights from the webinar or looking to build an AI cost management practice, Flexera can help you understand consumption, assign ownership and govern AI spend across your organization.
Transcript
Tracie Stamm 0:08 – 0:34
Hello, everybody, and welcome to our webinar today, The AI Cost Crisis.
We're here to talk about the AI spend that you can't see, own or stop. I'm Tracy Stamm. I'm Flexera's Senior Director of Product Marketing, and I'm joined here today with our featured guest, Tracy Woo, Principal Analyst from Forrester Research.
Tracy Woo 0:35 – 36:35
All right, Yep, I'm Tracy Woo. I'm one of the main cloud analysts at Forrester and I look at cloud from the perspective of Day 2 management.
So cloud cots, hybrid cloud, cloud governance, but most importantly AI cost management.
It is amazing that it is I think 95% of the calls that I have today, despite all of these other areas, everyone is interested in this.
Everyone has questions about it.
I just had the very specific niche questions from like things like just overall value realization to things like AI cost structures to how do we re-architect our anthropic contracts because that's also been a huge area as well since it's a shift its pricing model.
So just to jump into it, you know AI has exploded across industries and just to give you a magnitude what this looks like, this is some of our Forester data.
As far as what is generative AI adoption look like, 82% of individuals enterprise AI cost decision makers said that they have one or more generative AI application in production.
Another 76% of have one or more agentic AI app in production.
Now I would imagine that the agentic AI side of this will start to overcome and overshoot just overall generative AI application, especially because agents are the ones that are really driving the cost right now of AI.
Now if we look at the overall spend, it's about $1.1 million right now.
And this is an average across generative AI, Gentech, predictive AI spend in total.
Now this is small relative to cloud spend annually, cloud spend, we have it about 35 million annually.
This number here is just a AI costs over time.
So it's not even annually.
It is small relative to cloud spend, but when you think about the growth that has happened, we've had about a 40% increase year over year.
When I talk to organizations, they anticipate that their growth will be about 5 to 9X next year and that is a pretty universal number in that range.
So the cause for concern around AI has really started to grow.
And when we look at some of our outlook data here, we'll continue to see that growth.
By 2030, we expect $124 billion in generative AI spent in total just on AI software.
And then generative AI spend as a percentage of overall AI spend, we expect it to reach almost over half or over half by 2030.
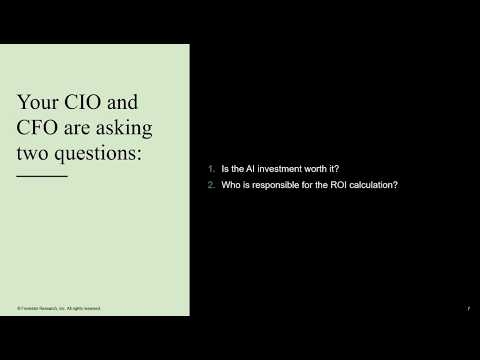
So these, these questions that are coming up, your CIO and your CFO, they're asking 2 questions.
Now this, these are seemingly small and simple questions, but they are big answers and big responses that people don't have the answers to yet.
And with if they say that they have the answers, it's they are not doing it correctly because no one knows how to do this right now.
And when the first one is, is the AI investment worth it?
And the root of that question is what is the value of this AI?
And does all of the other fully burdened costs justify the investment itself?
And then the second part of it is just who's responsible for the ROI calculation because the ROI side of it gets very tricky.
Unit cost is a very tricky thing to do.
You, you can say directly attribute specific costs, like if you have a Model 4 specific use case, you can attribute that model cost to that use case.
But what if there are three dozen 20 different use cases that are accessing one model?
How are you going to start attributing those costs?
Now, almost all of the models, well, OK, they charge by tokens.
There's only a few that will start to break down the tokens by image, by video, by text.
Most of them don't even do that.
And even when you're breaking down those token costs, you aren't necessarily able to attribute that to specific use cases.
That's when it becomes very valuable to be able to do that, and that's when you can start to optimize and pull on those different cost levers.
Now, if you don't know how to do that, then it becomes much more difficult to do that.
That's just mono cost.
What about databases, storage, all of these different areas, Infrastructure itself?
If you're sharing a specific GPU cluster, who's going to get that level of costs?
And then the last part about it is just who's responsible for the RORI calculation.
Because if you're looking at an overall AI economic model, for most parts, it makes sense to have this Federated AI structure where you have an overall AI enterprise governance standard, overall AI taxonomy and standards.
But then it makes sense to have this forecasting and budgeting happening at the use case level.
But what happens with all of these shared resources that are being funded by IT?
Are they responsible for the RA calculations?
Do they work together with the business teams?
That's created a lot of confusion there.
So the thing that is happening though is that FinOps teams are really rising to the challenge now.
This is from the State of FinOps survey from the FinOps Foundation, which is where FinOps team are they taking on AI cost management.
If you're just looking, two years ago it was less than half and now it's almost all of the organizations are looking at this.
The spend is relatively small, but there are definitely organizations where their AI spend is equal to their cloud spend or even outpacing their cloud spend.
And that will continue to happen, especially when they're using more and more agentic AI.
So what's driving the cost here?
Now we at Forrester, we like to define it in five different cost domains.
Specifically we're looking at applications.
So the development of the applications itself, integration testing, any sort of observability that you need to have, any sort of upgrading with the security side of this, any sort of ongoing maintenance, any AI related applications itself.
Then there are the models itself.
We'd already talked about that as well, but choosing frontier models versus foundation models versus SLMS, if you're doing that and you've already API consumption of inference tokens or reasoning tokens or caching tokens, all of that comes from the model cost itself.
And then there's agents, which I've already mentioned this a few times, but they're the biggest spenders right now and they, they will be especially outpacing agents versus humans, which is why you're also seeing these AI costs vendor or AI vendors starting to switch to a consumption based model.
Now it was always going to be consumption based.
They were really trying to hook you in with these flat fee fixed tier type areas.
But when you're looking at things like Anthropic where they are charging now, consumption based offer cloud code and they're charging an overall access cost, they are trying to offload that cost especially back on to you because of agents.
Agents are charging much, much more than a human could even putting in commands at the CLI.
And then there is data platforms itself.
So the ingestion, the preparation, the storage retrieval, any sort of databases, if you need to have any sort of data warehouses or data lake houses, governance or frameworks that you need to put into place.
So there any sort of cleaning of the data or standardizing of the data and then the infrastructure side of this.
So it's a huge cost lever.
It's one of the ones that are the most difficult to optimize.
Certainly you can do things like optimize your GPU, your clusters, you can scale and put your workloads on one container versus multiple containers.
You can standardize on a specific landing zone to help with that specifically.
But as far as your cloud provider, even maybe your storage preferences, any capacity commitments, those are things that are largely set in time.
You can start to do things like using Ptus or Gsus or MU's, which can help with that.
But if you're on multiple cloud providers, they all have different ways of managing their commitment, like so for instance, Google is probably the most granular as far as reserving your capacity commitment.
But and, and it does give you priority for those that are reserved versus on demand.
But AWS doesn't do that and Azure doesn't do that.
And they make you choose specific models.
So it's hairy because it's not like you're reserved instances and your savings plan where it's generally A commoditized structure across the cloud providers.
So when we're looking at these things and I already talked about managing some of the AI costs, but what are the issues that people are seeing now to delineate them clearly?
AI costs, they are everywhere.
Where is the crux?
It is all of the AI costs.
It is in everything and things like stack cascade.
So like 1 AI interaction can set off this train of interacting with vendors and different costs and different billing cycles and that and it can just keep on flowing.
So one that there's all of these specific things where you're calling all of these different technologies, you may not actually have visibility into the line of that technology that's being called.
There may be agent multipliers where you have different steps, different tool calls, different model calls, different retries.
If your agent is inefficient, if it is not effective, it may be continually calling over and over and over again and creating the same inefficient loop.
The design of it itself.
So model size, context, any sort of rag or caching, any latency hosting, any sort of capacity.
Depending on how you architect the design itself, it can affect how the cost is using a frontier model versus using a foundation model, or choosing an overall frontier model versus choosing a mini model versus choosing an open way.
If you're not caching, if you're not doing semantic prompting or other areas, this can create a lot of issues as well.
Inconsistent meters.
We talked about this already.
So AI interactions can create this inconsistent billing models across tokens, requests, throughput, storage, subscriptions.
That makes it very difficult to normalize the AI costs overall,
Value isn't necessarily spent.
So if you're spending it doesn't necessarily mean you're getting value.
Like for instance if you're if you're trying to measure how effective a copilot is and you're looking just at adoption numbers and frequency of usage, it may be that it's inefficient usage.
You may have employees that are putting in non standard or overly large prompt requests and that's not necessarily showing value, that's just showing we should spend.
And then there's variable usage.
So adoption, prompt, output length, things that we had talked about before.
There is a variable usage that happens internally with employees that are trying to get specific outputs out there.
So for instance I had one company that I spoke with where they had one employee that asked for one query and they had said search all of the documents so that we can find this one specific area.
And what they ended up doing was searching 15,000 documents, which called $30,000 in cost for that one request.
So all of that is there's the human variable that creates these huge amounts of costs and then shared services.
So we talked about this before where the allocation of it is very difficult, being able to shared models, shared data platforms.
And then there's also just a fragmented ownership of it because right now the AI cost has so many different levers and it requires different levels of expertise and skills.
Your FinOps team doesn't have all of these skills right now, not necessarily.
They should even say understand these things like say, if you're using an open weight model, your FinOps team shouldn't be saying, Oh yeah, you should also be thinking about mixture of experts and low rank adapters.
Even like creating things like KV cash or having different levels of guardrails are setting up your AI gateway.
These are things that are not the responsibility of your FinOps team.
It's not the responsibility of your finance team.
It goes into the product developers and they should all be teaching and learning with each other.
But it makes it much, much more difficult because who is actually owning the cost and who's responsible for managing that cost.
Now the different challenges that come within that, we did talk about some of these specific areas, but to give you a feel for what real world numbers look like, this is some of our survey data here.
We've have 30% that have just had visibility being an issue from embedded AI charges.
Now embedded AI is the AI capabilities that you turn on within an enterprise application.
So these are things like ServiceNow now assist sales force, agent force or sales force, Einstein, SAP Jewel.
You don't have visibility into that.
You may just have a fixed fee that is tacked onto your subscription.
If you're lucky, a lot of times these get embedded into the actual subscription itself.
So if you're getting charged by consumption or by the API call, you don't really have a way to be able to affect that cost.
31% have difficulty forecasting, and I would argue that's actually a much higher number.
What I've gotten is that some people have just given up on the forecasting and they've said, well, we don't know how to forecast.
So we just added 3X to all of our forecasts.
And at that point, all you're doing is forecasting to a budget.
And that's what a lot of people are doing right now.
So when they say they have a handle on forecasting, it just means that they're just budgeting.
36% have said that they have visibility or lack of visibility from untaggable resources.
There are lots of cloud services that are coming out that are not taggable right now.
And so it's been difficult to get into the visibility at unit cost side of things.
Now, what about resources like things like SaaS costs or like these embedded AI costs or API calls?
How do you tag those things?
You need a third party cloud cost management tool to be able to do that.
And the easiest way, is really through virtual tags to create that level of abstraction layer.
And then 33% with unit economics.
This has been a big area and it is what's the gating issue with costs, with ROI, with value realization, with justifying a business outcome because of things like shared costs, 24% just don't have knowledge.
Like I talked about before, your FinOps team doesn't need to have knowledge and doesn't necessarily aren't aware of all of these different optimization and cost levers that are out there.
And then last 39% just say it's difficult to collaborate with AI costs.
You're adding in more personas.
So cloud costs and FinOps, your, your essential members were your engineering, your business lead, maybe an executive person, your FinOps person and IT sometimes procurement.
But then all of these business units that are running these Pocs and experimentations.
I have clients that are just saying, well, our businesses are just buying their own NVIDIA GPUs and running around and experimenting that.
So there's also a lot of shadow IT that's happening right now, which makes it very difficult to get a handle of view of just what is our overall cost and is there real value there.
And to provide you with some of the numbers of when we ask people who owns your AI Technology Strategy and this is the numbers that we get.
There is not one role that specifically dominates that you would think CIO/CTO that makes sense or what about CEO?
But these numbers are less than 25%, all across the board and there are lots of different roles that are sprinkled in there.
So when you're thinking about what does good look like, if you're thinking, all right, well, the first part about cost management is really around visibility.
If you have visibility, then you are at least knowing where you where you're getting those costs.
Now it does make it difficult when teams are running off and doing their own spend and there is a lot of that right now.
This happened with cloud because there was a lot of Pocs and so people were saying here is this technology, try to figure it out, try to figure out a use case that is largely gone away with AI cost.
It's a whole new can of worms.
It is cloud on steroids.
It is cloud times 100.
So you know, the first thing you want to do is you have one system of record making sure that you are looking at every transaction.
You will want to work with your finance team to make sure that you're maintaining that.
This will be 1 current record of your AI applications, any agents that are called on that are created on models, data services, data platforms, data warehouse infrastructure that's used, any vendors, any sort of embedded AI features, regardless of whether it is shared or attributable.
You will want to have an overall inventory of this and you want to update this inventory as workloads move from experimentation to production.
And I would say don't rely on your cloud tags for everything.
You will want to have a specific use case ID for every single one, and you'll want to have two different ledgers for that.
So you'll have an AI cost Ledger, which is just looking at things like cost per token, cost per call, cost per specific model, or cost per subscription.
And then you have your AI value Ledger where you're looking at things like forecasting, unit costs, different sorts of experimentation and value realization there.
And the combination of the two will be important.
And the reason why you keep that separate is because they will come to the surface at different layers within the development life cycle or within the use case life cycle itself.
But you'll want to keep this both in check.
The other thing too is that you'll want to have specific metrics that you're scoring against.
So you'll have one that's just on the technical side of this, the operational side of this, and the business value side of this.
And you'll want your operational component to be the connecting layer between your technology cost and your business value cost.
So your technology cost could be things like your token cost, it could be your like cost per model call or your cost per storage.
Your operational cost will be your cost per unit of work load.
So it could be things like your cost per transaction, your cost per document stand, and then your business value could be things like your cost of risk avoidance or your cost of or your cost avoidance.
And all of these different areas are meant to be a connecting layer where you have a scorecard, a specific use cases for that.
And the use case ID needs to be persistent throughout all of this.
Any sort of allocated, any sort of allocatable by use case, tying that cost to business value as much as you can to do that.
It will be important for, for being able to see this value realization.
Now part of the issue is, is with these things like clear owner tracing the cost across the stack is that as far as cost management tools go, it's relatively nascent in its capabilities.
There are, there are like sums I can do session tags or do tracing across from say the prompt all the way to the output.
But for the most part, this is quite immature.
However, the market is changing and developing and even within the first six months or the past six months, we have seen started to see more than just AI cost visibility.
There is more that is helping you with the value side of things, getting down to the granular unit costs of things, being able to assign token costs or token spend the individual unit of token to a specific model used and then some that claim ROI and value.
I wouldn't trust that because it's very difficult to do that right now.
I don't know anyone that can do that, but you'll want to do, you'll want to use that as well as observability data right now.
The other side of it too is getting in a, a gateway to be able to provide that governance and framework.
Now all of these things are coming in at different angles, but they haven't necessarily converged together.
And that's the important thing is you need something that is pulling all of those insights together.
Now the governance side of things is a little bit trickier because it is more obvious and is very much like your cloud spin-offs and your cloud costings.
It follows the same tenants of individual accountability, cross functional collaboration and real time data decision making.
But however, these are the most difficult things to achieve because when you take this job of managing AI costs or managing cloud costs, what they don't tell you is that some of your biggest roles and responsibility are to be a therapist, to be a mediator, to be a PR person.
Because ultimately you were the connecting linchpin between all of these areas, between engineering, finance, procurement, IT, where they are, you are explaining to them what is the intention of all of these other teams while also communicating with them why are costs this way?
Here's how you manage costs.
Here's how you optimize it.
Here's how we showed cost avoidance, things that will be really important there, the things that are similar with FinOps, which is regular meetings, standardized taxonomy, standardized governance and framework as far as policies and guardrails.
So that means things like standardized landing zones, having governance as codes, say within the CI/CD pipeline, having even reviews that happened even before the spend occurs itself.
So a very shift, shift left approach, making sure that you have racy chart for who does what.
So clear roles, clear decision rights.
Do people need to be informed? Like so, for instance, you may have clear roles about engineering developers and business unit users may be the ones that have the biggest say within the architect.
So your developers may be the ones that are accountable.
Ultimately they're in charge of it.
Your business developers are ones that are consulted or could be vice versa.
And then inform could be your program managers, which are the ones that are driving and trying to push these programs use cases along.
But they are just the schedulers, they are just the budgeting person.
You still need to keep them on the same page so that you're all working towards the same goal where 1 isn't necessarily gating the other.
You want to make sure that you have rules matched to the life cycle stage.
So and then that's the same thing with tagging too.
You want your tags to continue to develop and change as it moves through the life cycle stage because it will change specifically for when you do that.
You may even have tags that are just saying this is test and dub, this is prod, this is non prod, this is pre prod.
There could be other things too.
Your model might change, your model selection might change where you were storing that data, specific regions, if you're using it on the cloud or not, and then a business case required for production.
I would argue that the business case actually needs to happen in a bunch of different areas.
So a lot of organizations are just denying Frontier model uses.
They're saying you have access to foundation models.
If you want to use a Frontier model, then you need to ask for that exception and not the other way around where some, everyone has by default Frontier model and then they get slapped on the wrist when they're using a Frontier model and they shouldn't be doing that.
And then also just regular investment reviews.
So these could be monthly business reviews or quarterly business reviews where you have the different teams that are building up the use cases present to an executive team.
So one Page 1 slider which is talking about are we on track for costs or are we not on track for costs?
If we're not on track for costs, where are we?
Are we red, yellow or green?
Red would be that remediation needs to happen immediately.
And these are things like you have exceeded your budget.
All spending seizes until you figure out ways to optimize that cost or that use case gets shut down completely because there's no value that happens there.
Yellow would be you need to show that you have a path to remediation, but that you haven't you haven't implemented it yet or you have plans to do that or you're in the process of doing that.
And then green is just you are good to go all green light ahead.
Now it is important to celebrate the green use cases and give them as much attention as the ones that require immediate remediation as well, just to make sure that you're showing what good looks like, but also you're celebrating what the good work is as well.
And then the last part about it is control.
So control is where you are starting to get your approval of service and configurations.
It's partly governance, but it's also overall your executive team that is saying these are the specific services and configurations that you're allowed.
Your finance team is coming in involved as well and they're saying this is your overall AI cost budget.
These are the usage limits that you have.
And these could be things like finance side, it could just be your spend, but it could also be limits like how many times can you retrieve your data?
How many times can you call a model, how many tools can you call just these?
These small limits can help to control the cost in a way that starts to add up in a meaningful way.
Automated anomaly detection.
Now, the thing about anomaly detection, especially with AI cost, is you won't want it to be fairly loose right now because your AI cost can spike at a moment's notice.
And especially when you're in this POC experimental stage where you don't necessarily know what guardrails we should put in place.
We're just trying out different, like different scenarios, different Pocs.
That's an area where anomalies may be acceptable for that specific area.
So the automation of the anomaly detection is really when you're in the production stage, production style use cases, that's when you have more consistent budgeting, you have more consistent forecasting, you have use cases and a baseline that's already established.
And then on top of that though, you will want to make sure that your anomaly detection is able to filter out white noise because it's not useful.
If every little spike creates an anomaly, then it just becomes something that people ignore.
So make sure that the threshold is high enough that when there is anomalous spent that you're able to pay attention to it.
Now there are things that you can do and this is the same thing within cloud FinOps that's happening within AI costs.
And I say that there's one policy everyone should put in place which is if you are outpacing your spend within a small period of time.
So say for instance something like that prompt that created a $30,000 charge, you need a policy that is shutting it down.
So if your if your budget on a monthly a cadence is $10,000 a month for AI cost and over the weekend you are spending $5000 of it, there needs to be a policy that automatically shuts that down because something went seriously wrong.
And so that's when you get into the alerting, throttling and shut down.
And the alerting and the throttling, those are things that should happen and precede your shutdown time.
The alerting should be tracking the cadence of your spend based on your forecasts.
So there should be alerts.
There could be throttling where if you're almost at like 75% of your budget that it starts to shut down specific things like access to specific models that more expensive, or it starts to limit even more of your tool calls that you have in place.
All of these eventually should be automated.
At this early stage.
I would probably not automate these things right now unless you're already at production scale.
Guardrail is built into the deployment itself.
So the same thing as says code where you're making sure that there are specific tags that need to be put in place.
There are specific use cases that you're only using.
There are specific scenarios where employees only have access to specific parts of the application and then prompt guardrails itself.
This is mostly right now through AI gateways where you are saying you're putting something in front of any sort of interaction that you have, whether it's a chat bot where there's an agent, you're making the request and there are specific things like you can't make your request to verbose or if it's if it's redundant with another call or a call that happens with regular frequency that there's some prompt caching that happens.
And the same thing with if there is a similar response, it always gets asked that you have some semantic caching that happens as well.
It could be things like choosing also that you are only accessing specific areas that aren't infringing on PII.
All of these things are small little things that can have big meaningful impacts, or maybe not so small if you're calling on a A, if you're using a prompt that's charging 10s of thousands of dollars.
Now with these things, what do you do about it when you are going to walk out the door right now I just unloaded a lot of stuff on you.
What do you do now?
If you haven't done anything within AI cost management, these are the areas I would recommend.
So when you're going from day zero to day 30, there should be a baseline for your full overall AI system spent.
You will need this baseline of before AI versus after AI to be able to recognize things like incremental margins, any sort of any sort of transformational change, any sort of value realization.
All of those different areas will be helpful.
Now, the way you do that is if you can have isolated use cases or controlled environments so that it's not attributable.
A lot of different variables aren't attributable to that.
What you'll want to do is make this very simple.
Prioritize one to two use cases, inventory costs across all of your layers of AI spent, and make sure that you have a way to be able to categorize that.
You want to categorize by the source of cost, by the use case, but also by the core values that you have, the specific values that you're trying to reach like improved productivity, cost avoidance, reduce errors or inefficiency.
All of these different areas you'll want to start categorizing by the outcome that you want.
And then from day 31 to 60, that's when you'll want to start putting in your governance value and funding.
So you may still be in POC, you're probably still in POC or experimental stage, but that's when you want to start building out a standard taxonomy, standard tags, things like standard cost structure of how you want to manage those costs as well as like a minimum viable scorecard for different unit costs that you're looking at different, different KP is and metrics that you'll want to see performance versus latency versus cost.
In this scenario, you will want a value use case budgeting.
You'll want to establish essential usage tiers.
Who has access to what and when do they have access to it?
Does permissions turn on or turn off as you move through the development life cycle?
And then from day 61 to 90, you'll want to standardize this control.
So you'll set budgets, you'll set request level limits, and these will be things like if you exceed your budget, who are you going to request that from?
Do you have a standardized process to be able to do this?
Is there an exception handling process if you want to append more tags or change some of the tags for specific use case?
Are there anomalies and escalations that can happen as a result of that?
So you'll want to be able to detect those anomalies, but also be able to filter out the white noise.
And it'll be difficult to do that at first.
So there'll be a lot of manual implementations, but it should look something like when you have an anomaly, you're able to provide an alert.
And what you'll also want to do is to be able to score it yourself as well.
So how much time does it take from the incident happening to the alert itself?
And being able to time that level of efficiency is one thing.
Once you start to have that spend, are you throttling that spent and then any sort of shutdown, if there's a shutdown, why is that happening?
And then making sure you have a pass remediation and you'll want to review this quarterly, at least quarterly, I would recommend actually monthly right now.
So that's what I have for today, and I'm going to throw back over to Tracy.
Tracie Stamm 36:36 – 36:57
Awesome. Yeah, Thank you so much. Tracy.
I've been just chewing on an earlier stat you shared that 30% are struggling with visibility to some of the more subversive costs of AI, like embedded charges. I wonder if that figure is even underrated given those days.
Tracy Woo 36:57 – 37:38
I suspect many aren't even aware of those embeds. Yeah, I think you don't know what you don't know. And also there's a bit of ego involved.
I yeah, there's certainly a lot of FinOps teams that are saying like we don't know what to do and we don't know how to handle this.
But also there's the education component of it.
Like we don't know what to look for as far as visibility goes.
And then there's also just like, no, we got it handled.
There's some hubris there involved.
So I think like those three different factors certainly make it make that number quite low, but I would say that it's probably much, much higher.
It's probably in the 90 percentile or 90 percentage range.
Tracie Stamm 37:39 – 38:03
Yeah, yeah, definitely.
Well, that's a big reason why we're doing this webinar in the first place.
OK, Given that we do have a couple of questions submitted ahead of time here.
The first poignant, where is AI cost accountability actually landing?
We saw where the strategy lands in the org, but how about the real onus to manage it in service of that strategy?
Tracy Woo 38:04 – 39:28
Well, right now the right now it's fragmented and that was something that I had alluded to earlier, which is the, the spend of AI is in an interesting time right now.
It's like cloud in that people are saying go free and figure out something to do with it.
So the spenders are often the ones that are managing it right now, partly because it's a small amount of spend, partly because they're just trying to be given some freedom to do that, and then partly because they're the ones that understand the cost levers.
Your FinOps team doesn't necessarily understand it right now, nor should they get involved until there is more than just a small pilot out there.
So it, it kind of becomes this weird hand off, like kind of like hot potato hand off where it's like I'm not managing cost.
You're managing cost or you're managing cost. Overall there should be some executive oversight for that. And it depends on where you are.
So if you're at production scale, it should be your CIO. But if it's at the POC stage, it should be your CTO or your CAIO. And they, they may be ones that are just overall accountable, but the ones that are managing it and responsible for making sure the costs stay under a certain specific level should be your business unit owners.
Tracie Stamm 39:29 – 39:40
Yeah, yeah, you said FinOps isn't ready quite yet to receive that baton, so to speak. What more do they need to own it, to be ready to own it?
Tracy Woo 39:41 – 42:16
The so the FinOps team needs to start expanding. And right now it is people that are managing cloud spend, managing commitment capacity, have right sizing, some tie ring knowledge in place.
But once you start getting into areas like you can kind of see this with the container costs, when you're managing container costs and now you're trying to get into, you know, horizontal pod scaling or cluster right sizing, these sort of areas become much more DevOps question.
And so the DevOps persona is getting involved within the container cost side of this.
And then similarly with AI, it'll be the same thing where you'll start to see your AI, your data scientist, your ML teams get involved.
And so your FinOps team will start to expand because your FinOps lead and your practitioner, that's not their job, nor should it should it be because then they're over rotating on this area. That's a small amount of spend.
It's a very difficult question and it's hard to understand. It has potential to be a huge amount of spend, but it isn't right now. A lot of the spend and management is still focused on cloud spend, on overall IT spend. So to give you an like an idea of the magnitude, overall annual IT spend right now on average Is $300 million. Your cloud spend is $35 million.
And the number I quoted before was AI spend is at $1.1 million. That's not annual, that's just overall AI cost. So there's a lot of focus on this area because it's very scary of how quickly those costs can escalate. Just like everyone quotes the Uber story, but it's a huge cautionary tale out there.
Like, you know, you look at X and people get on the get on the keynote stage. Like what we saw with Accenture, they're talking about one of their customers spent $250,000 in one day on AI costs.
It's these sort of things that really freak people out. Most people aren't there yet.
So the FinOps team needs to be focused on just overall cloud spend with some specialized focus on AI costs.
But really it's going to be this collaboration between them and the business teams and your ML teams that are working to manage this and get the skills and visibility. And eventually you'll have someone from the AI costs, the AI spent.
So your data scientists that will sit within the FinOps team or at least share a part of their responsibility.
Tracie Stamm 42:17 – 42:51
Yeah, definitely.
And that Uber story, just to quickly summarize, was one of the, you know, more public stories this year 2026 for token maxing. They said, you know, to their staff, please go innovate, don't worry about the expense. And in so doing blew their their IT budget by April.
So that's the story that Tracy, I know you're referring to there before I'll go to the next question.
Before ACIO can judge if AI is paying off, what do they need to see?
Tracy Woo 42:51 – 44:28
Well, they need visibility.
So that that goes down to that first slide that I was talking about. As far as you know what to do next, you need to get visibility. You need tags to get tagging, you need knowledge and skills.
How do you do that?
There are, I mean, it's really on the tooling side of things. So the capabilities there are still nascent. However, most tools can ingest the cost. So you can just see it where the development is happening right now is at the attribution layer and at the forecasting layer and then at the optimization layer.
But you, you need to get visibility into all of your AI costs to have a baseline of what is your AI, what it like, did it actually help to improve something?
Did it help you to improve the value of it?
The other thing too is if you have this value that you realize, let's say like you were able to create some capacity with, now your engineers are free to do much more complex and more innovative tasks with some of the more menial tasks that are automated with AI.
It is only value realized if you are able to convert that time to something else.
Cost of 1 is another one. It is only value realized if you are able to take that cost and direct it towards say some something else that's innovative or some other effort out there.
Tracie Stamm 44:29 – 44:51
Yeah. And time saved is notoriously difficult to quantify and justify, but it is certainly felt in the organization.
OK, where's the biggest cost lever that most organizations are leaving on the table
Tracy Woo 44:51 – 44:52
The cost driver or cost optimization?
Tracie Stamm 44:52 – 44:51
Probably optimization.
Tracy Woo 44:54 – 49:09
OK. So it depends on, it depends on where you are with AI. I have actually a quick plug for this report that I have coming out. It's a major AI cost decisions that a CIO needs to consider. And I have AI categorized into three different areas.
There is bring your own AI, which is and that's down to two specific areas.
So there's AI where you're bringing in different components to largely put together the AI stack.
And then there is the bring your own AI where you are building on top of an AI development platform.
These could be things like a bedrock or vertex and you are pulling in things like something from a data lake house or warehouse or a different ERP data to be able to build up an AI capability.
Then there is your embedded AI, so AI that you turn on based on a capability like with Salesforce or with ServiceNow Analysis or SV Jewel where you have that capability, it may or may not be exposed to you.
And then the last part about it is the copilot, the SaaS, the SaaS subscriptions.
Now the biggest cost lever changes based on where you are.
If you are just looking at bring your own AI, one of the biggest and easy, I'd say easiest levers right there because it's easy to understand technically, but it is difficult to implement is just choosing the model, choosing the right model. Now choosing the model and using a model router only makes sense on the AI cost development side of things.
If you were looking at the customer facing use case and the chat bot side of things, the use cases get so wide and varied that actually using a model router for that doesn't make any sense.
In the AI development side of things where you have very specific tasks like debugging, running the specific code, testing a specific level of code, those are areas where calling different models can make sense. This doesn't happen within the development life cycle though. It happens at the runtime of the program itself.
So that's one thing within bring your own AI. The other things too, things like being able to reserve capacity, that's another big cost lever. So like like what I was talking about before with Gsus and Mus and Ptus, like across the different hyperscalers.
And then when you, when you look at embedded AI, it gets really tricky because you know, how do you gate that?
Now one of the one of the like, like easiest sort, I'd say obvious levers is limiting the API calls itself and then also limiting the prompt as well.
So putting in guard rails around the prompts.
And that's the same thing with these employee AI assistants.
Now it's mostly subscription based right now, but like we've already seen Copilot switch to a consumption based model and they've been obscuring the, the like token cost by providing you with credits.
And the credits are a way to like I think give you less control over being able to manage the performance and the cost of it.
So a big part about that is just making sure that you have visibility to be able to tag to a specific use case.
But also unfortunately, when you do start to get to a consumption based model and they are, they are not providing any AI at the standard level.
They are just saying if you want any sort of AI capabilities, you must use these credits.
You do have to make a cost decision analysis each time.
For smaller use cases, it may be something that's automated and goes through very quickly, or you have a specific set of approved use cases where you can just spend on those AI capabilities.
But for larger use cases, more complex use cases, that's when you will need something that helps review on the SaaS side of things as well, like it's just idle users, license rightsizing, like these are all very ITAM specific things that you can do that are like more standard things to help with the employee AI assistant optimization side.
Tracie Stamm 49:10 – 49:19
Awesome. Yeah, yeah. And that credit system becomes another bespoke currency that has unfurled with its own maybe dynamic math behind it.
Tracy Woo 49:20 – 49:45
Yep. Yeah. And then Speaking of dynamic math, I, sorry to interrupt, but I forgot to mention this.
You know, even with the token costs, with the models, the tokenizers are changing under the cover all of the time, and they're not telling you what it is. So your, your margins are inherently dynamic and changing all of the time. And it's just something to be aware of, which is why it makes forecasting unit costs so difficult to do.
Tracie Stamm 49:46 – 49:58
I just ran some analysis and the tooling came back to me and proudly asserted that it did the analysis in 21 steps. I don't really know what 21 steps means or why I care.
Tracy Woo 49:59 – 50:06
Yeah. Yeah, that's a fair point. Yeah, I see the steps. And I was like, that's interesting. All right. What's the result?
Tracie Stamm 50:07 – 50:18
Right. Exactly.
OK, Well, lastly, you know who what, what are you seeing of the market solutions available that can be helping people with some of these challenges?
Tracy Woo 50:19 – 50:20
So there. So I mean like you know, like Flexera and the other tools out there, there's a lot of visibility ingestion.
Like you're starting to see more like optimization on specific areas like GPU cluster ride sizing is something that's been widely available for now. I'm starting to see more like trace, trace tagging type capabilities.
So that's another thing that you'll wanna look for, model rounding, but model rounding specifically for the AI development side of things, the gateway side of it.
So there's lots of different AI gateways where you're able to put these sort of prompts guardrails on top of them and you're able to do caching.
A lot of them also have model routing capabilities within them. And yeah, it's a, it's a pretty nascent market right now, but like I said before, it's going to change. And within six months it's going to be a totally different landscape as far as the tooling landscape looks like.
Tracie Stamm 51:21 – 53:26
Yeah, yeah, yes and we find that most tools stop at the subscription or stop at the cloud bill. And you know Flexera already sits underneath all of it. ITAM, SaaS, FinOps on one common CMDB.
So our solution for AI cost management extends that same foundation to treat every AI consumer, human or even automated AI consumer like an agent as the unit of accountability.
So big thanks here to Tracy Woo from Forrester Principal Analyst. Really appreciate the research and insights that you are available to share with us today.
This is a perfect opportunity for me to close by highlighting the two sessions that we have coming up that dig into exactly some of the gaps that Tracy highlighted here.
The first is AI from budget plan to business purpose. This is all about how you've set the AI budget, but do you actually know where it went or what it bought you? We're going to show you how to close that gap. Consumption traced back to the human or the non human consumer that created it, all normalized into a single view and attributed to the team or the workflow responsible.
And then the second, which we'll make for the third in this series, is AI from accountability to action. Visibility gets you just an opinion, important, but not the whole story. A decision takes action, and the best action at that is automated.
So this webinar's the Road Map conversation all about attribution, tagging, thresholds and what it actually takes to turn Signal into automated control.
Dates and registration links are landing in your inbox and we hope to see you at both.
But in the meantime, thank you so much for joining Flexera in conversation with Principal Analyst Tracy Woo from Forrester.
Tracy Woo 53:27
Thank you for having me.
Let’s get started
Our team is standing by to discuss your requirements and deliver a demo of our industry-leading platform.